

JOIN OUR NEWSLETTER
About This Project
Summary
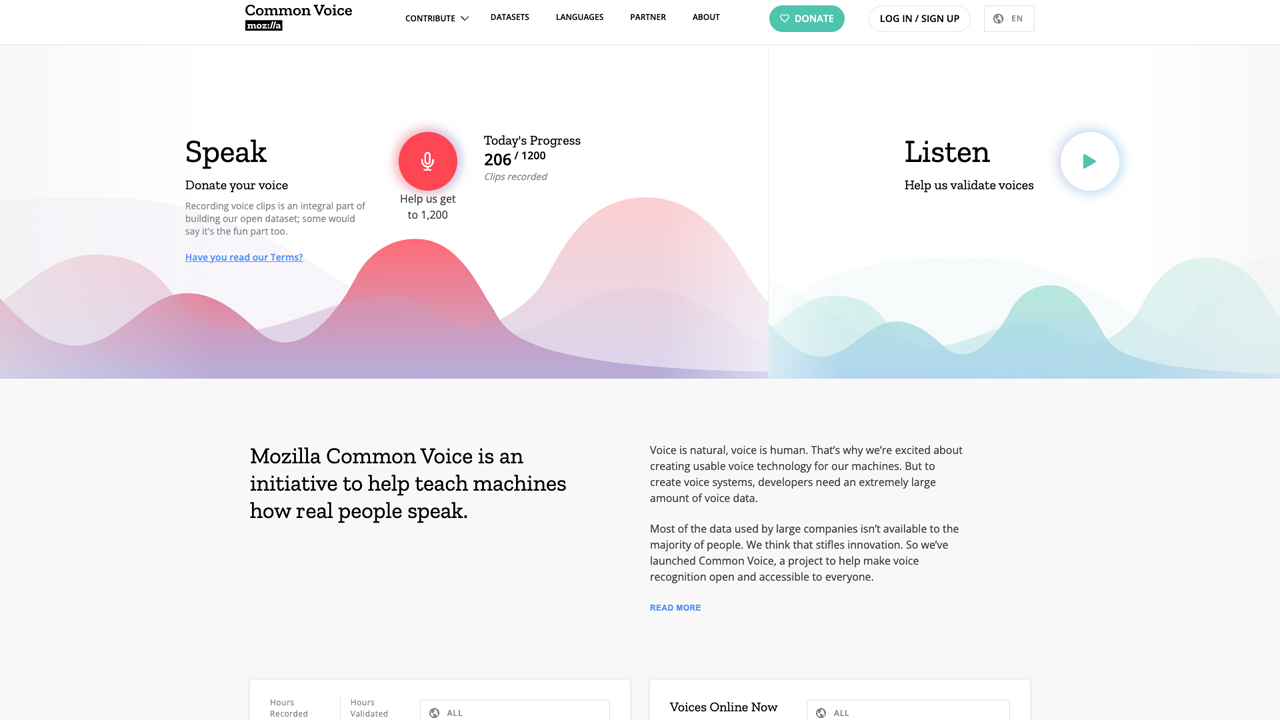
Common Voice is a global, volunteer-driven voice dataset aiming to democratize voice technology. Most existing datasets are proprietary and underrepresent non-English speakers, people of color, disabled individuals, women, and LGBTQIA+ communities. Common Voice empowers diverse voices, fostering an inclusive data ecosystem. The project captures varied speech, enhances text data quality, diversifies governance, and engages with open-source communities to promote responsible AI development.
Goals & Objectives
The Common Voice project enhances speech diversity, improves text data quality, diversifies governance, and engages open-source communities. Goals include supporting code-switching, ensuring quality text contributions, and exploring community-led data collection for equitable innovation.
Results & Impact
Common Voice has collected 30,000+ hours of speech data in 87 languages, making it the world's largest & most diverse open voice dataset. Certified as a Digital Public Good, it supports under-resourced languages and reduces bias in AI, fostering equitable and innovative voice technology development.
JOIN THE NEWSLETTER